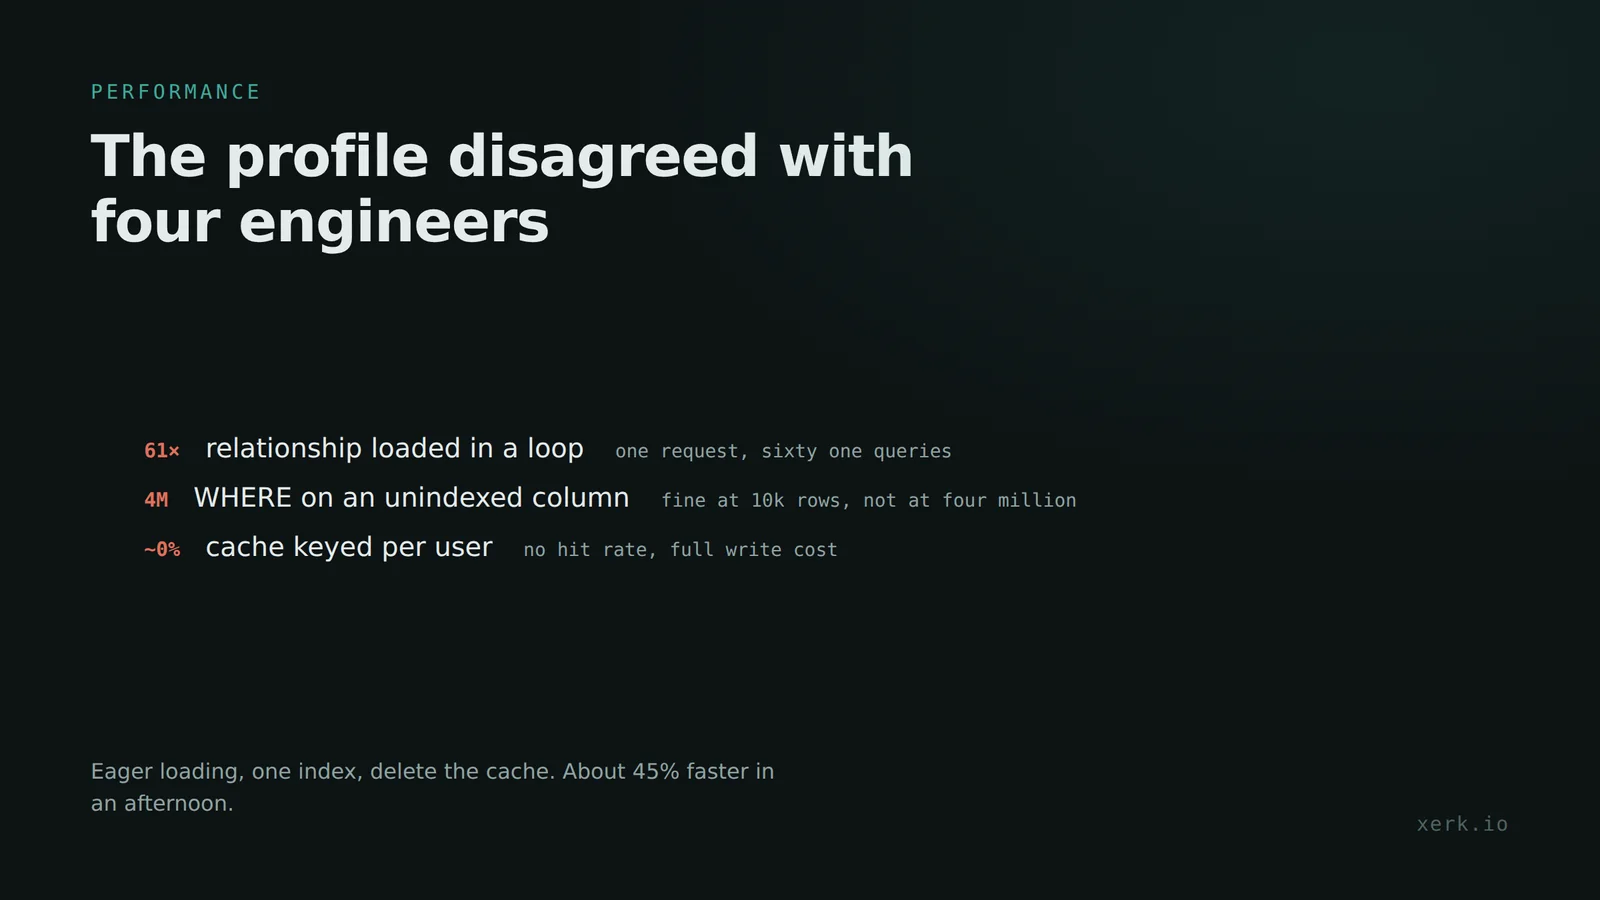
An endpoint got about 45 percent faster and I didn't write a single clever line of code. I ran a profiler, and it disagreed with four experienced engineers.
A week of guessing
The team had been arguing about this endpoint for a week. One person was sure it was the ORM. Another wanted to move the whole thing to a queue. Someone suggested rewriting it in Go, because someone always does.
I ran a profiler for twenty minutes instead.
What the profile found
It turned up three problems, and nobody had guessed any of them.
A relationship was being loaded in a loop, so one request became sixty one queries. The classic N+1.
A WHERE clause filtered on an unindexed column. That had been fine at ten thousand rows and was not fine at four million.
We also had a cache keyed per user, added six months earlier. Its hit rate was close to nothing, and we were paying the write cost on every request.
An afternoon of fixes
Fixing all three took an afternoon: eager loading, one index, and deleting the cache. Deleting a cache feels wrong, but one that almost never hits only costs you.
Why this stuck with me
"Use a profiler" is advice everyone nods at and then ignores. What I keep coming back to is that four experienced engineers each had a confident theory, and all four were wrong. Without the profile we'd have spent a sprint rewriting the wrong thing. Measuring first is boring, and it keeps being correct.
Building something like this?
I'm Ahmed Mamdouh, a senior full-stack and AI engineer. I reply within one working day.
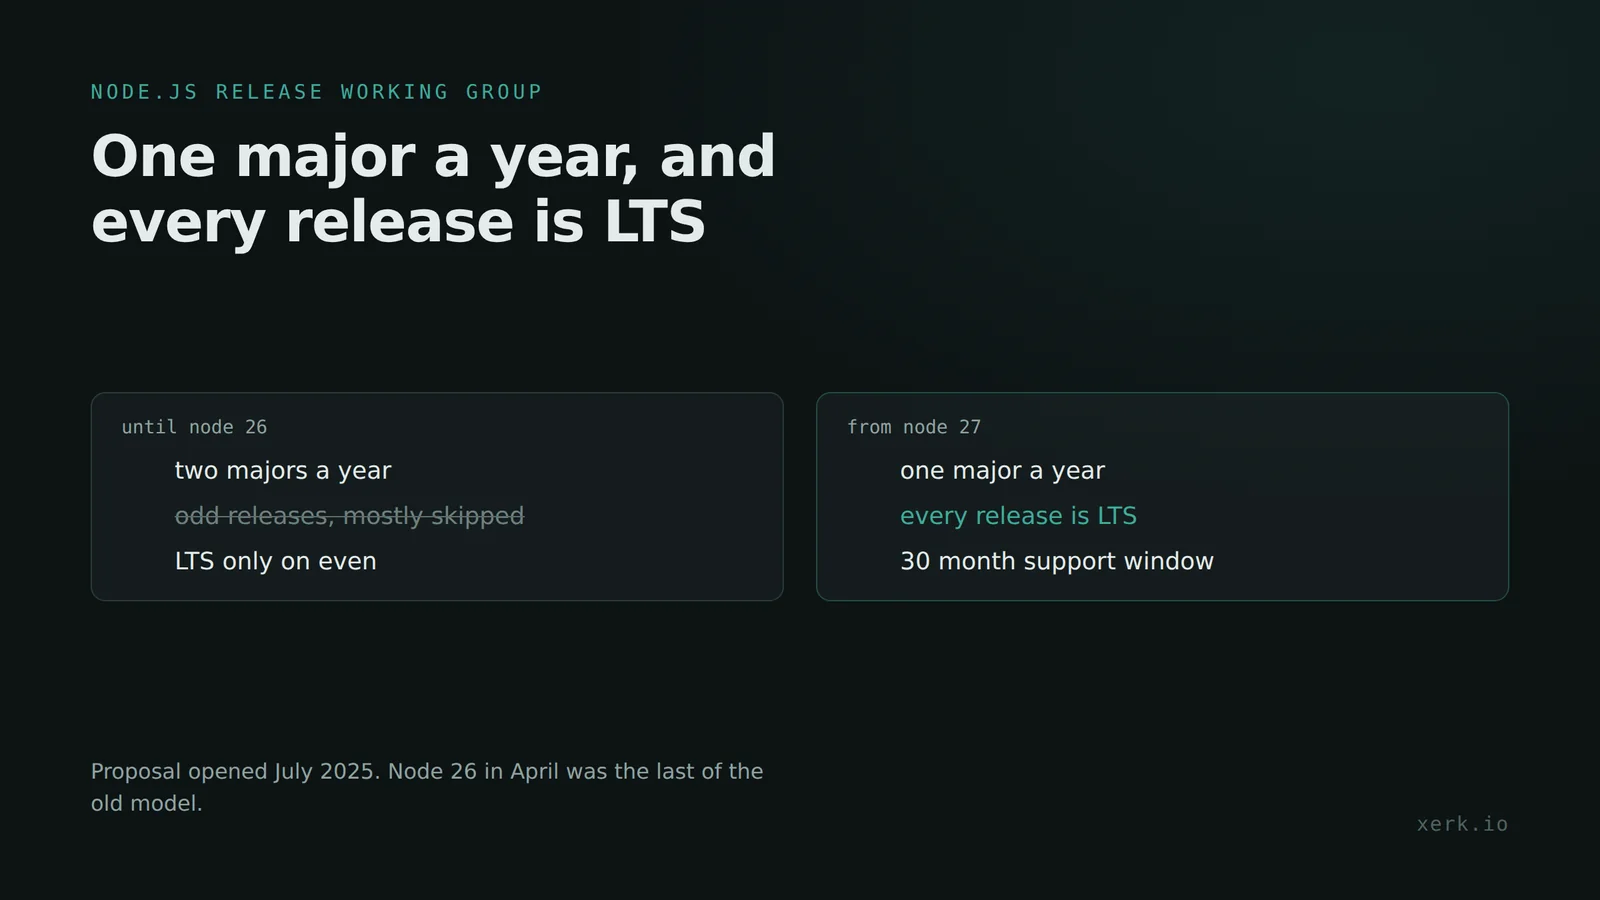
Node.js moves to one major release a year
From Node 27, Node.js ships one major a year and every release becomes LTS, ending the odd/even split most teams already ignored.
Mongo or Postgres is the wrong first question
Pick a database by your known access patterns. If you don't know them yet, pick Postgres, because it forgives wrong guesses best.
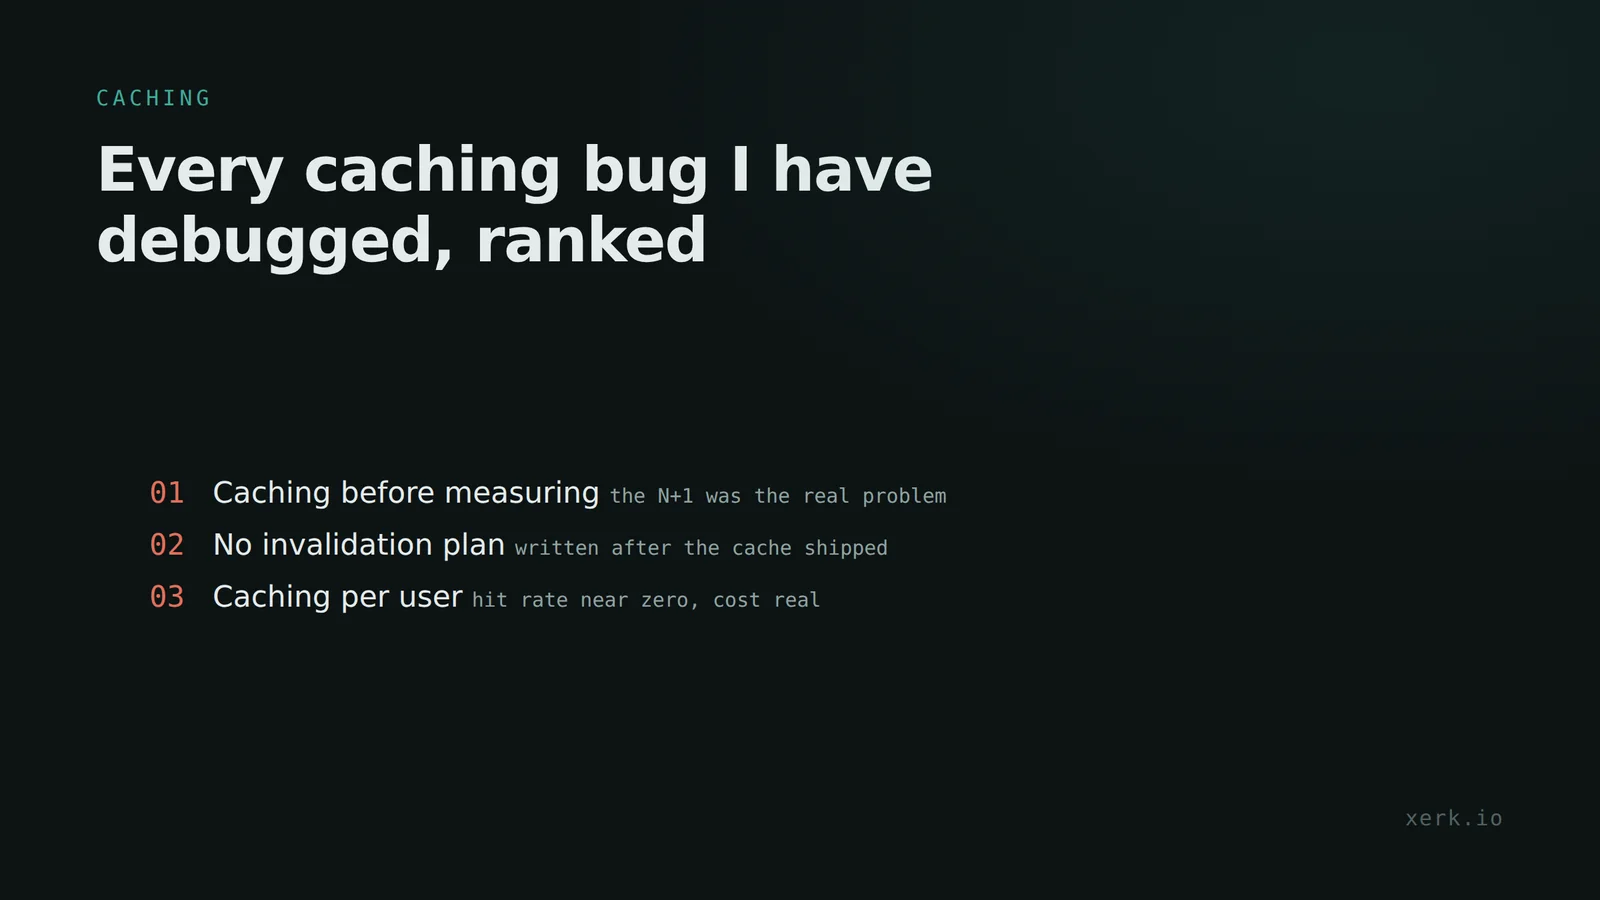
Caching mistakes I keep debugging
Before adding a cache, decide what invalidates it, measure first, set a TTL, and cache the expensive part instead of the whole result.