If your Node service doesn't handle SIGTERM, every deploy is a small outage. The fix is a graceful shutdown handler of about fifteen lines.
What happens without it
The pod gets the signal and the process dies on the spot. Whatever requests were in flight just end, users see a 502, and they blame the feature you shipped.
The fix
Catch SIGTERM, stop accepting new connections, let in-flight requests finish, close the database pool, then exit. Add a timeout so a stuck request can't hold up the shutdown forever.
const server = app.listen(port);

process.on("SIGTERM", () => {
  // Hard stop if something hangs
  const timer = setTimeout(() => process.exit(1), 10_000);
  timer.unref();

  // Stop accepting new connections, wait for in-flight requests
  server.close(async () => {
    await db.end(); // close the database pool
    process.exit(0);
  });
});
Keep that timeout shorter than your orchestrator's grace period. That way your own code decides how the process ends, and a SIGKILL never gets the chance.
Nobody notices
When you get this right, nobody notices anything, which is more or less the goal. Users stop getting a 502 every time you ship, and a deploy goes back to being a non-event.
Building something like this?
I'm Ahmed Mamdouh, a senior full-stack and AI engineer. I reply within one working day.
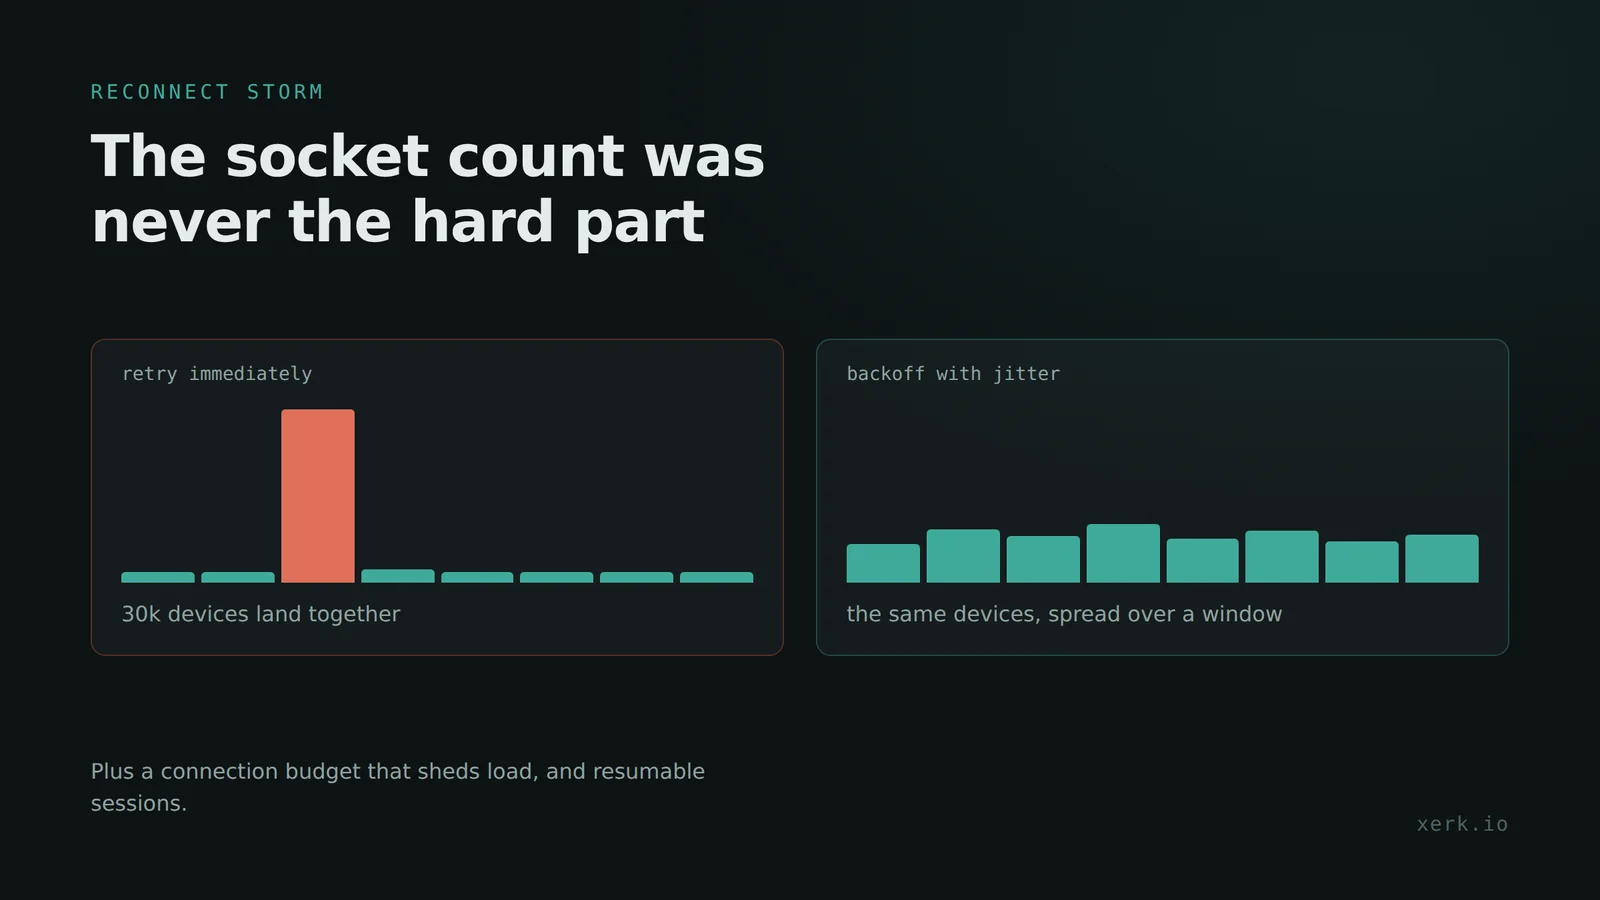
Scaling 100k WebSocket connections: the reconnect storm
At 100k+ concurrent sockets the count is easy. The reconnect storm is what breaks, and jittered backoff, load shedding and resumable sessions fix it.
npm v12 blocks install scripts by default
npm v12 no longer runs preinstall, install or postinstall scripts unless you approve them, closing a common supply chain attack path.
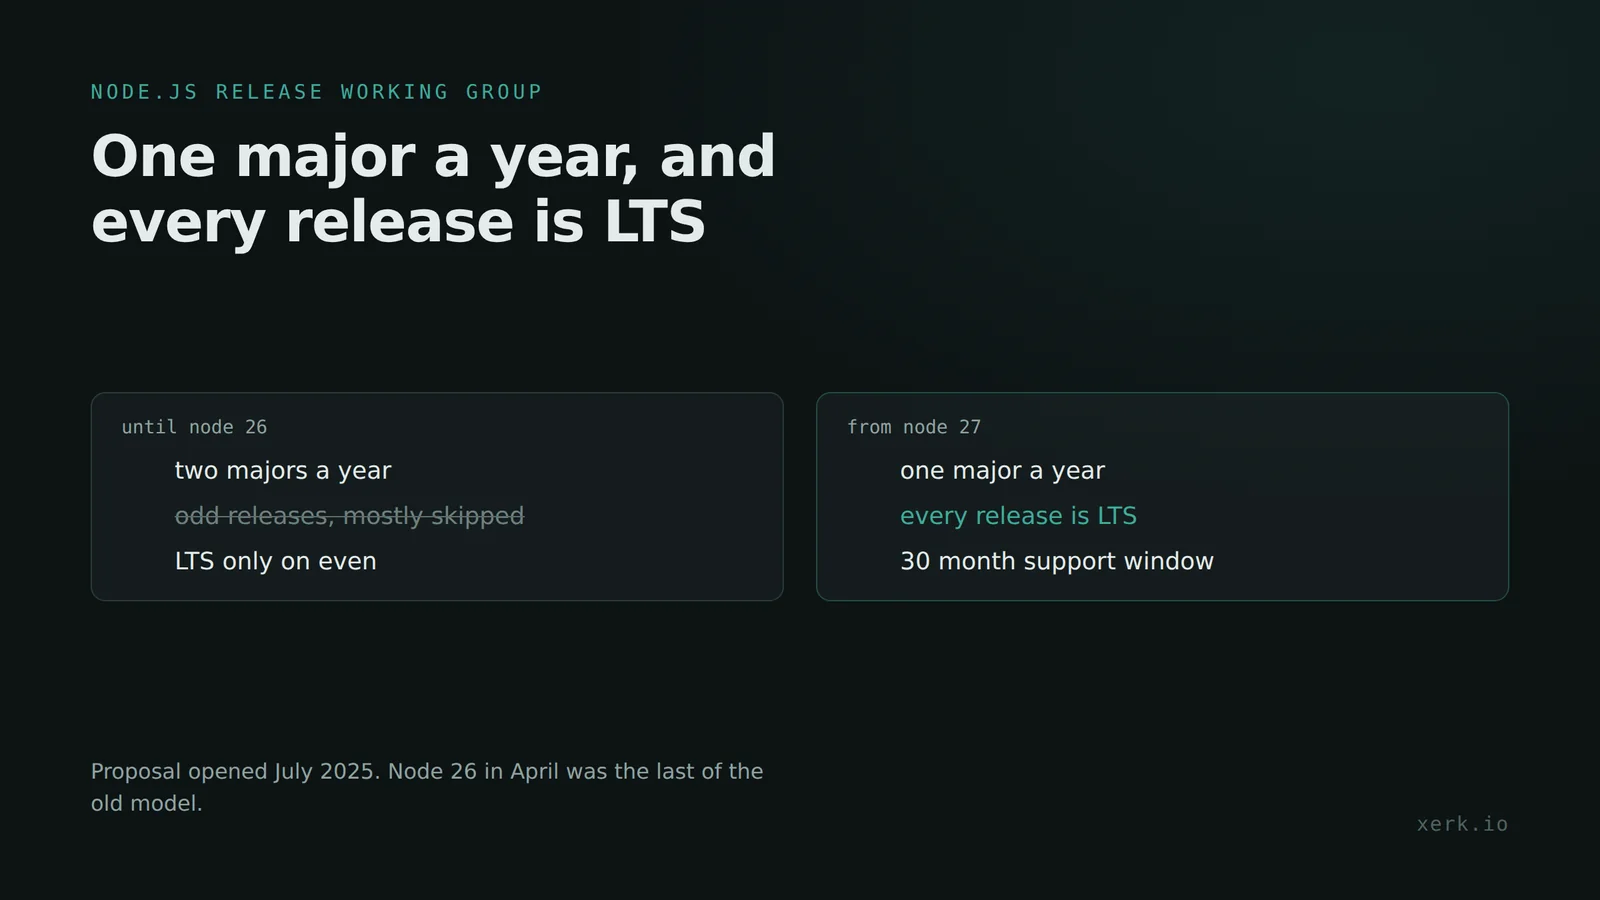
Node.js moves to one major release a year
From Node 27, Node.js ships one major a year and every release becomes LTS, ending the odd/even split most teams already ignored.