The gap between an agent demo and an agent in production shows up on the third tool call, when the API returns a 500 and the agent has already written half a row to your database.
Demos are one happy path
A demo shows one happy path. Production means partial failure, retries that must not double-charge anyone, and a clear rule for when the agent stops and asks a person.
I see plenty of agent architecture diagrams. I rarely see anyone talk about the three things that actually break.
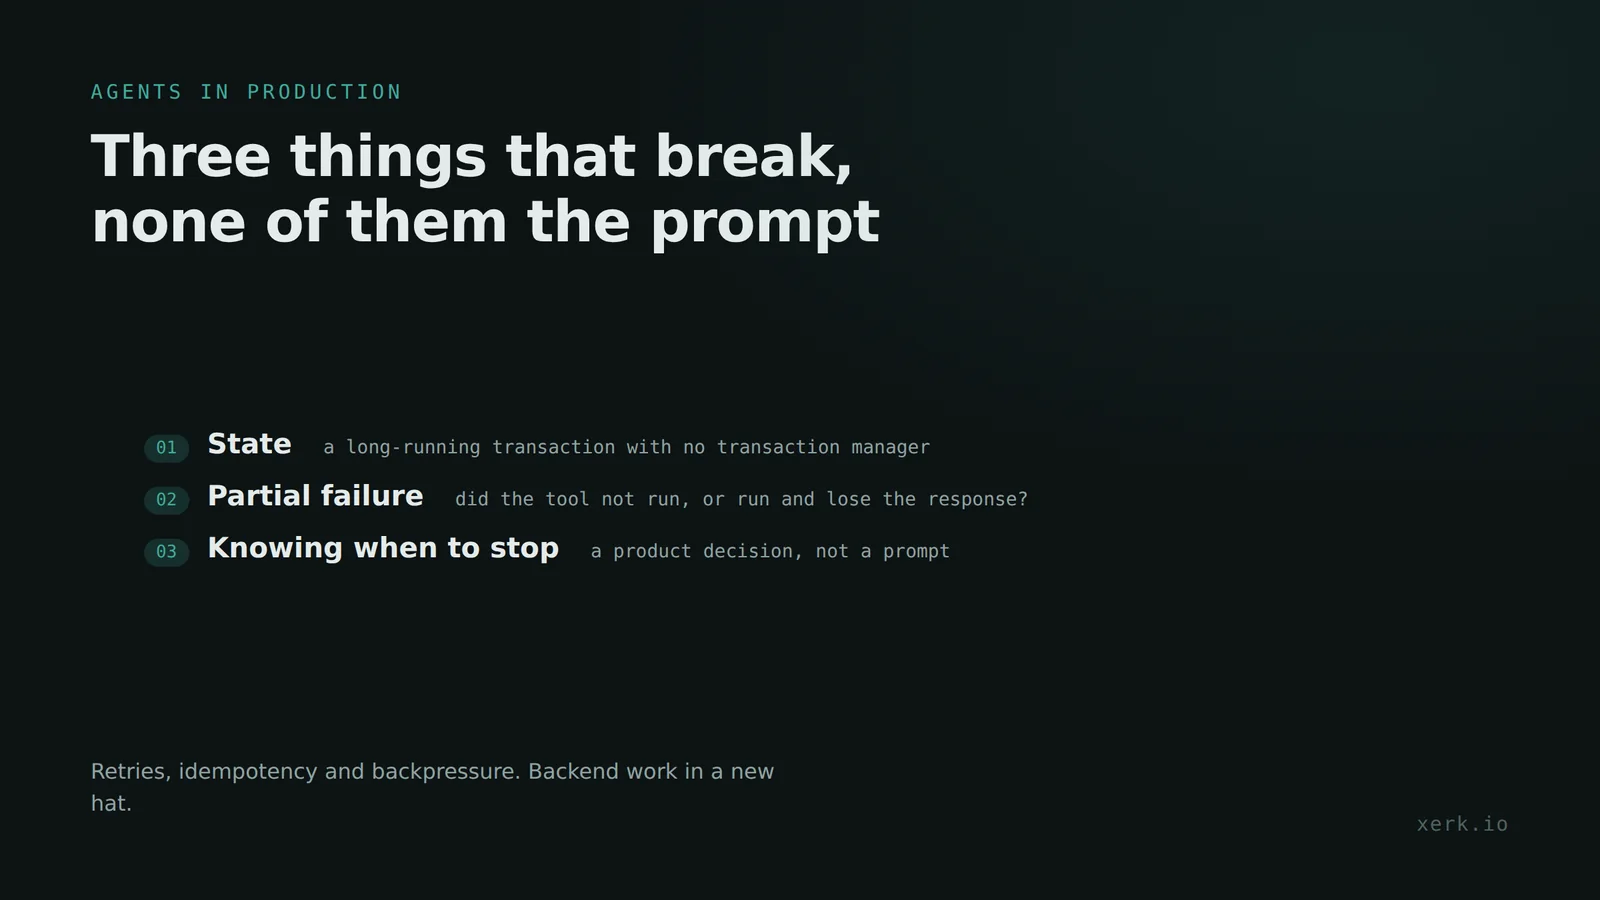
State
An agent that runs for ninety seconds and calls six tools is a long-running transaction with no transaction manager. If it dies on step four, something has to know that steps one to three happened. Most demos keep that in memory and hope. In production the progress needs to be persisted somewhere a restarted run can read it.
Partial failure
A tool call times out. Maybe it never ran, or maybe it ran and the response got lost. Those need different handling, and the agent usually can't tell them apart, so treat a timeout as an unknown outcome. That's why every side-effecting tool needs an idempotency key, the same way every queue consumer does.
Knowing when to stop
This one is the hardest. An agent that asks a human too often is a slow form, and an agent that never asks is a liability. Where the threshold sits is a product decision. It belongs in code where you can test it, and a line in the prompt is a poor place to keep it.
Nothing new
None of this is new. It's retries, idempotency and backpressure, which backend engineers have been doing for twenty years, applied to a new kind of caller. In my experience the model is the easy part.
Building something like this?
I'm Ahmed Mamdouh, a senior full-stack and AI engineer. I reply within one working day.
MCP went stateless, and that matters
The July MCP revision went stateless with OAuth 2.0 and OpenID Connect, so MCP servers can now run behind load balancers and serverless.
Claude output is now watermarked
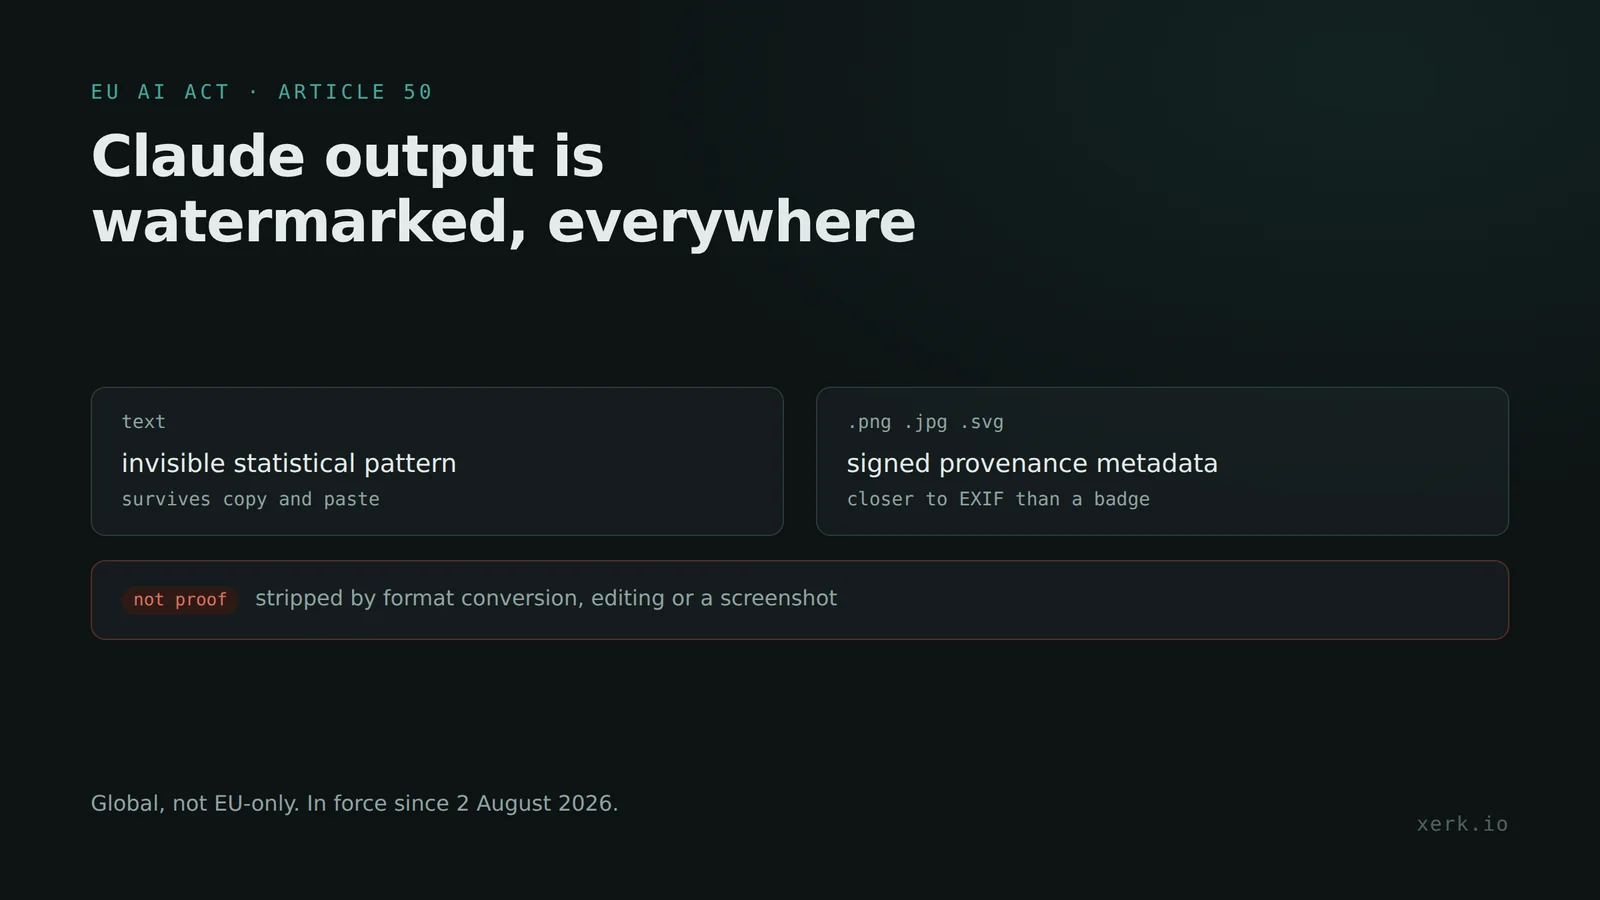
Claude output now carries watermarks and signed provenance by default. Tell your users, and never treat a missing watermark as proof.
At-least-once delivery means at least once
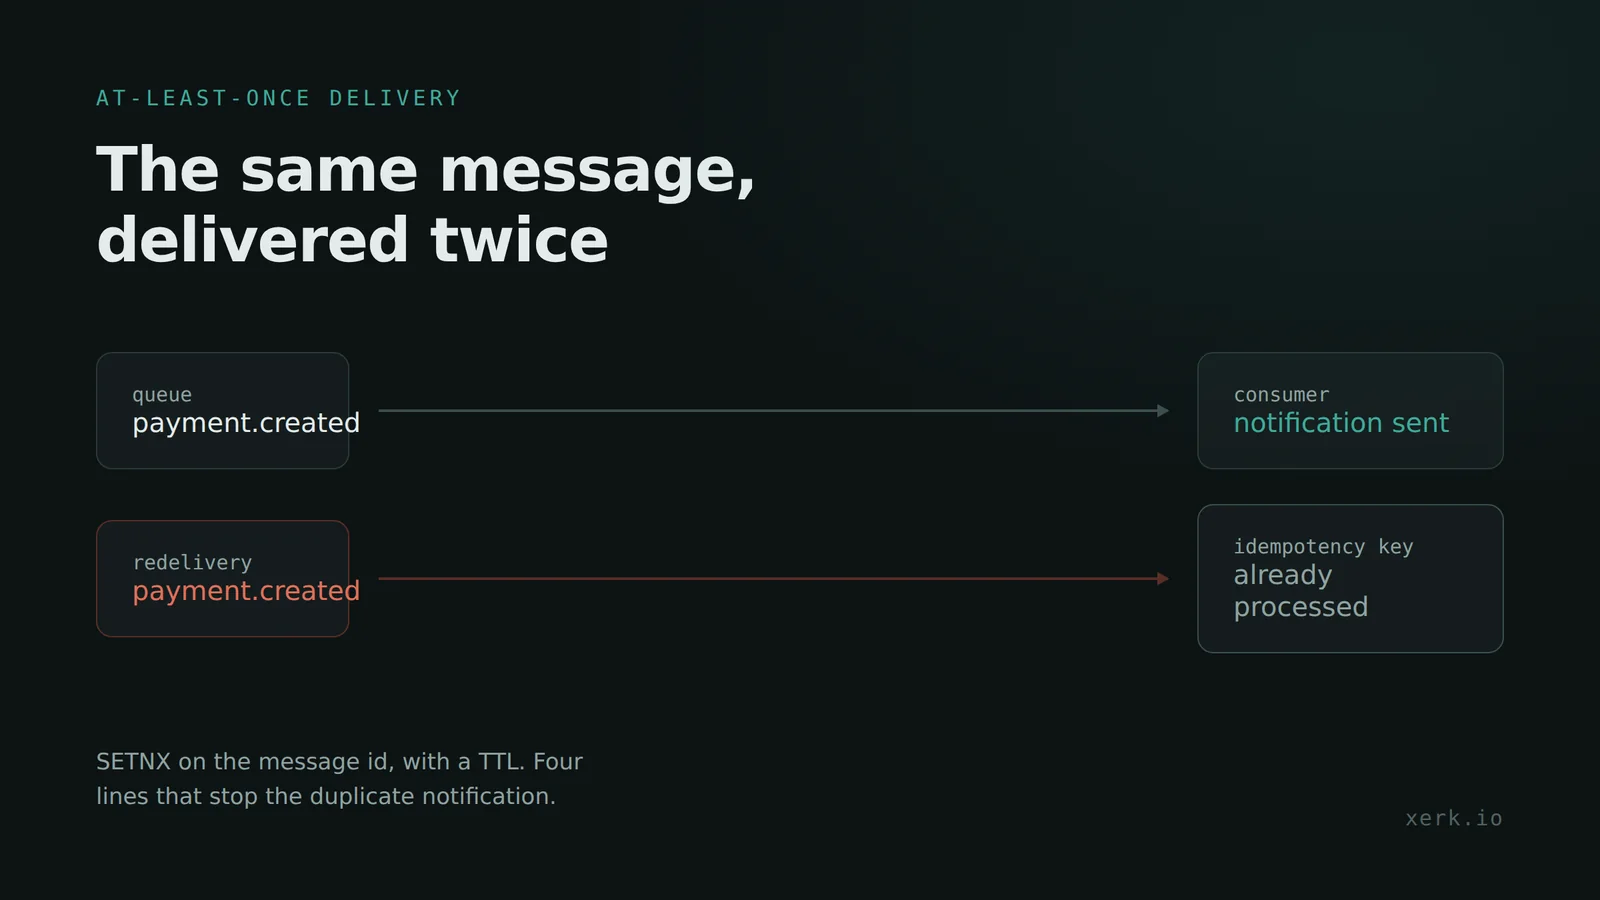
Every queue consumer eventually runs twice. Give each one an idempotency key from the message and check it before doing the work.