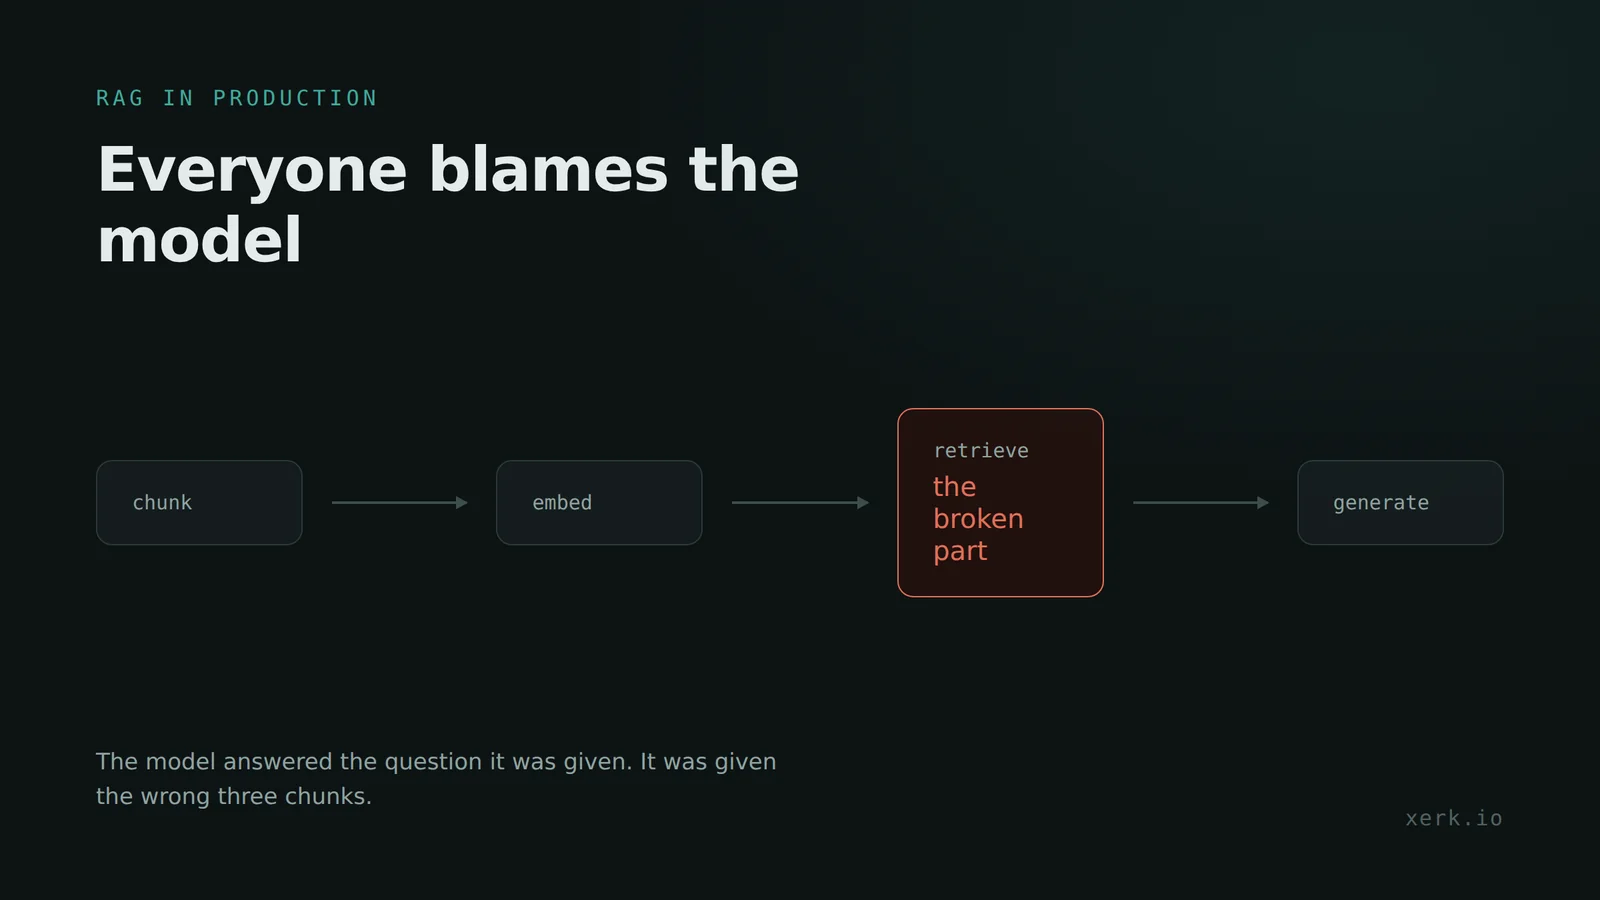
Everyone blames the model. In the RAG system I run in production, the model is rarely the problem. Retrieval is.
The model never saw the right context
The setup is the usual one: a vector database, embeddings over our documents, and an LLM answering questions on top. Whenever answers were bad, the first instinct was that the model wasn't smart enough.
Almost every time, retrieval was at fault. The model never saw the right context, so it improvised. Garbage in, confident garbage out.
Three boring fixes improved answers more than any model upgrade did.
Chunk by structure
Cutting documents every 500 tokens splits tables from their headers and answers from their questions. Chunking on headings instead fixed a whole category of wrong answers. A chunk should hold one piece of meaning, whatever length that turns out to be.
Filter on metadata before vector search
Half our bad answers came from retrieving the right topic in the wrong context. Vector similarity finds text that sounds alike. It has no idea which product, environment or time range you meant, so filter first and search second.
Run a small eval set on every change
Ours is 50 real questions with known answers. Not thousands, fifty, and it runs on every pipeline change. It was humbling how often a "small improvement" made retrieval worse.
The model is what people demo. Retrieval decides whether the answers are right, so that's where I'd spend the time.
Building something like this?
I'm Ahmed Mamdouh, a senior full-stack and AI engineer. I reply within one working day.